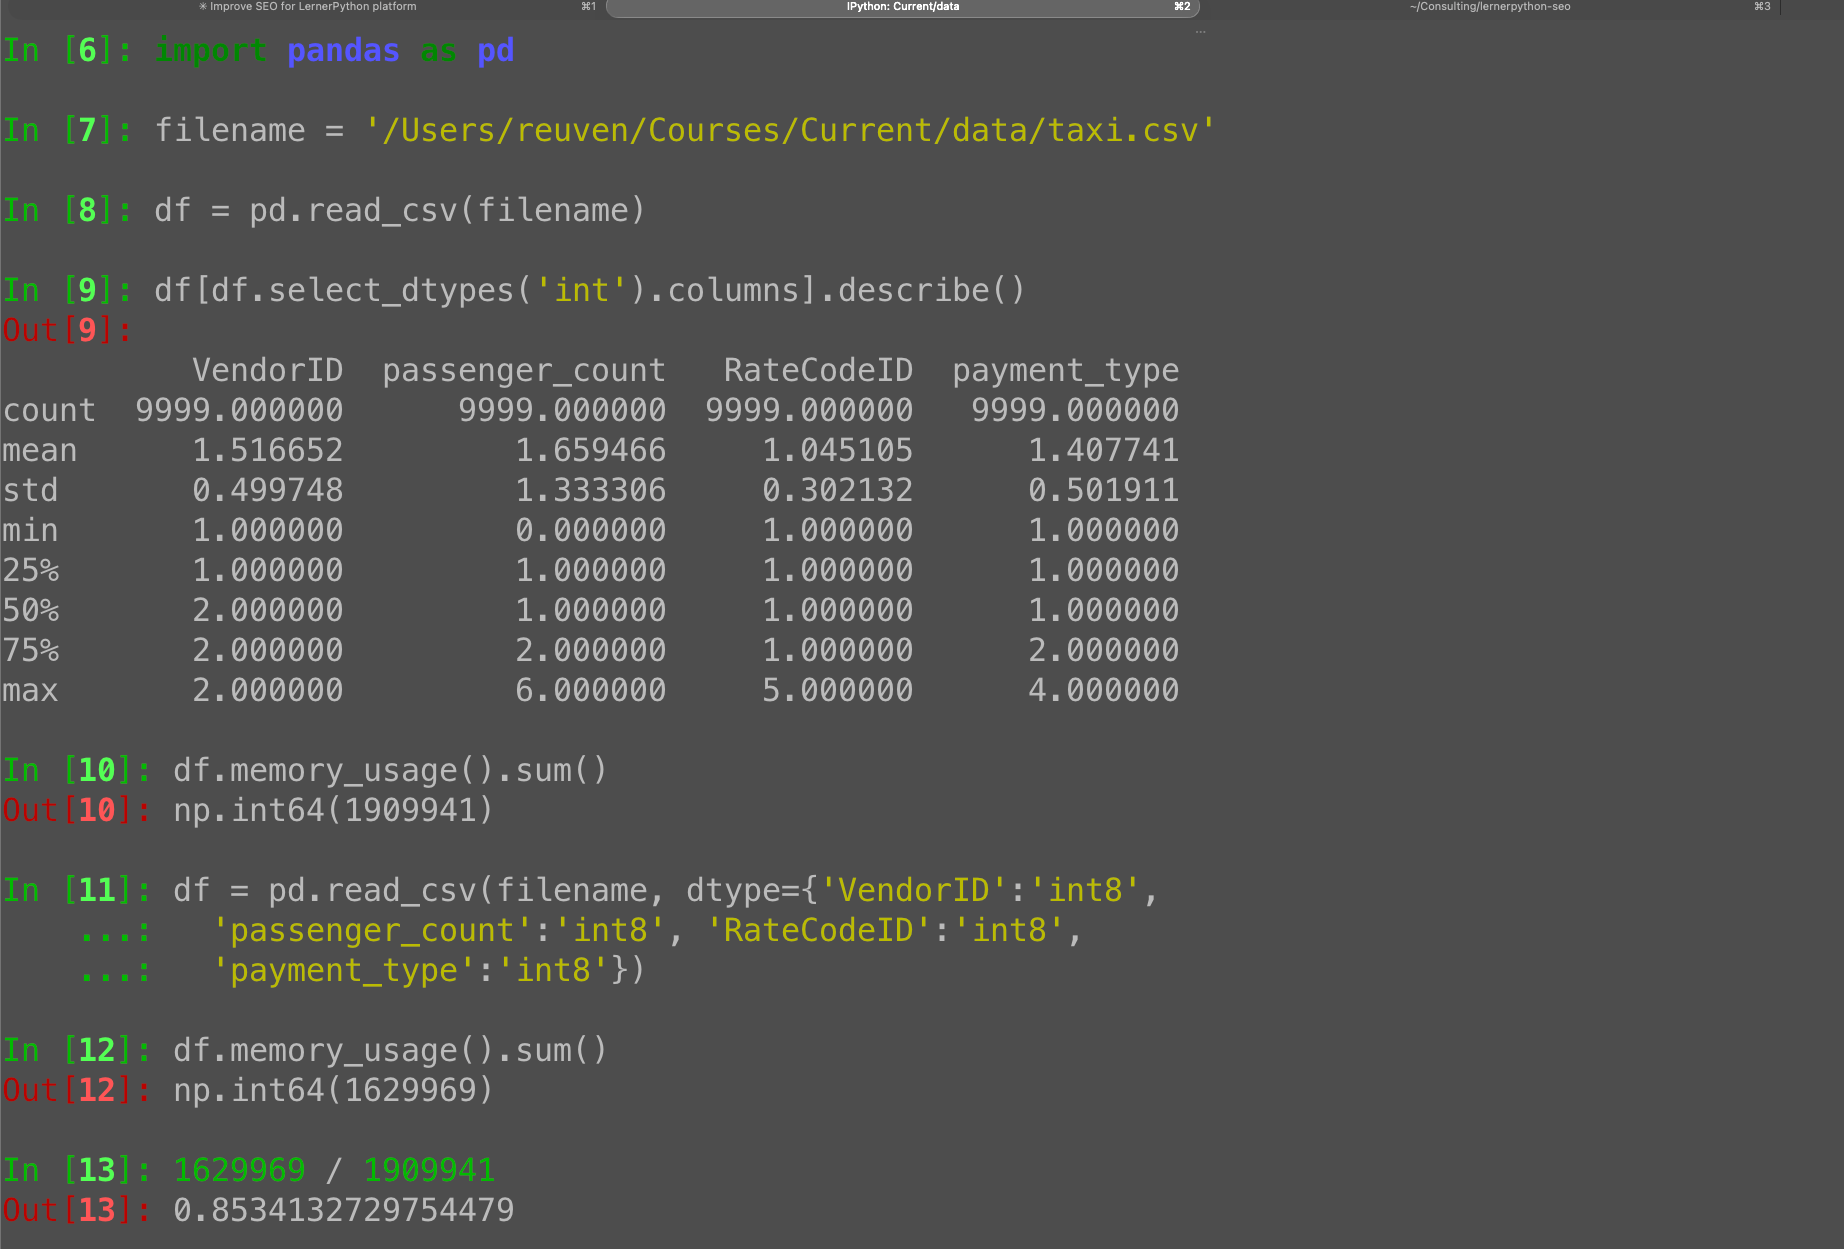
Reading a CSV into a Python Pandas data frame? Use the “dtype” keyword arg and a dict to specify dtypes, and avoid the int64/float64/str defaults:
df = pd.read_csv(filename, dtype={'VendorID':'int8',
  'passenger_count':'int8', 'RateCodeID':'int8',
  'payment_type':'int8'})