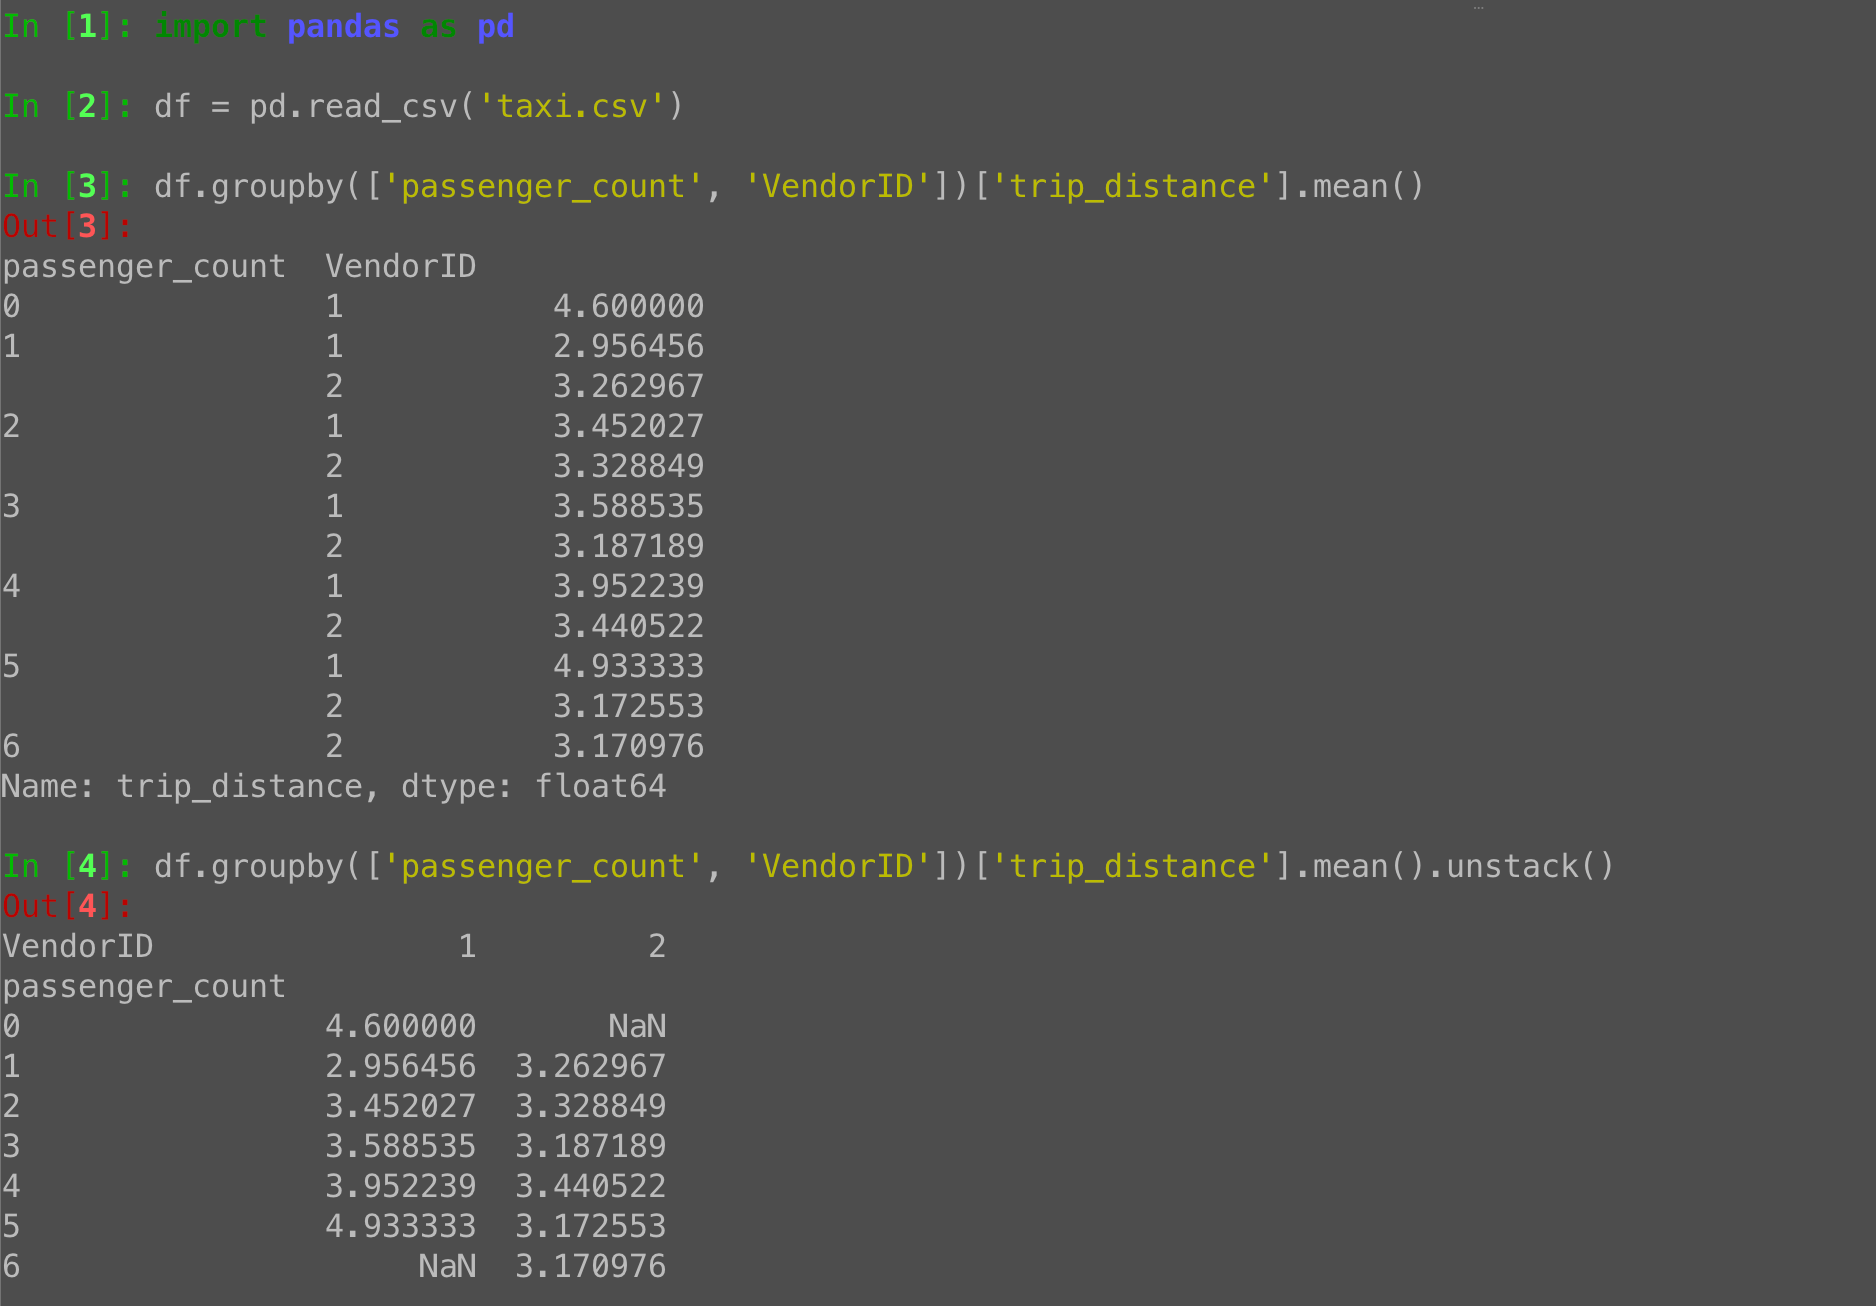
Invoke “groupby” with two categorical columns in Python Pandas, and get a two-part multi-index:
g = df.groupby(['passenger_count', 'VendorID'])['trip_distance'].mean()Turn into a data frame with unstack:
g.unstack() # index 0-6 (passenger_count), columns 1-2 (VendorID)